At the outset, I would like to separate socio-political concerns from the technical discussion of the subject. I can write a silly computer program, name it something ridiculous like "Head Hitler of the World", endlessly pump misinformation about what it is and how it might lead to the extinction of the human race, meddle with elections to install fascist leaders around the world, siphon off trillions of dollars from the world economy, and destroy a significant portion of the world's natural resources. The discussion about how evil I am and how I must be stopped is however, tangential to the silly computer program I wrote. This post studies the construction and behavior a similar silly computer program, omitting tangential discussions altogether.
Twenty-five Fields Medalists have claimed:
- Over the last few months, the mathematical capabilities of LLMs have improved dramatically, to the point that they can solve major outstanding problems in many fields of mathematics
This is as nonsensical as the claim:
- Over the last few months, the version control capabilities of
lshave improved dramatically, to the point that it can solve major outstanding version control problems
No, ls has zero version control capabilities, and you're the dunce for using ls instead of git here. Similarly, the mathematical capabilities of LLMs have always been, and will always be, exactly zero.
Many people misunderstand what mathematics is and isn't, and many believe it's something only a rarefied group of mathematicians does. Nothing could be further from the truth: mathematics is nothing more than the application of mathematical reasoning, and it is an essential function everyone performs in everyday life.
Take a simple statement I wrote about integer overflow:
- X >= Y is equivalent to X > Y - 1, and this holds trivially when Y - 1 does not overflow. When it does overflow, it must be INT_MAX, and the comparison would evaluate to false anyway.
Does it seem correct? We can use a simple software tool to check it, and it says incorrect, and prints a counter-example. This tool, which is a sophisticated version of a hand-held calculator, has mathematical capabilities. Similarly, another class of software, called proof assistants, has mathematical capabilities:
theorem and_commutation (p q : Prop) : p ∧ q → q ∧ p := by
  intro h
  apply And.intro
  · exact h.right
  · exact h.left
A proof assistant would check this proof and report that it is correct. You could think of the application of this code in everyday life as "Anna and Mike came to the party" being equivalent to "Mike and Anna came to the party": needless to say, but even a toddler would reason about this correctly.
What underlies the notion of computation is an adder, which adds two numbers encoded as 0s and 1s. A circuit of a half-adder looks like this:
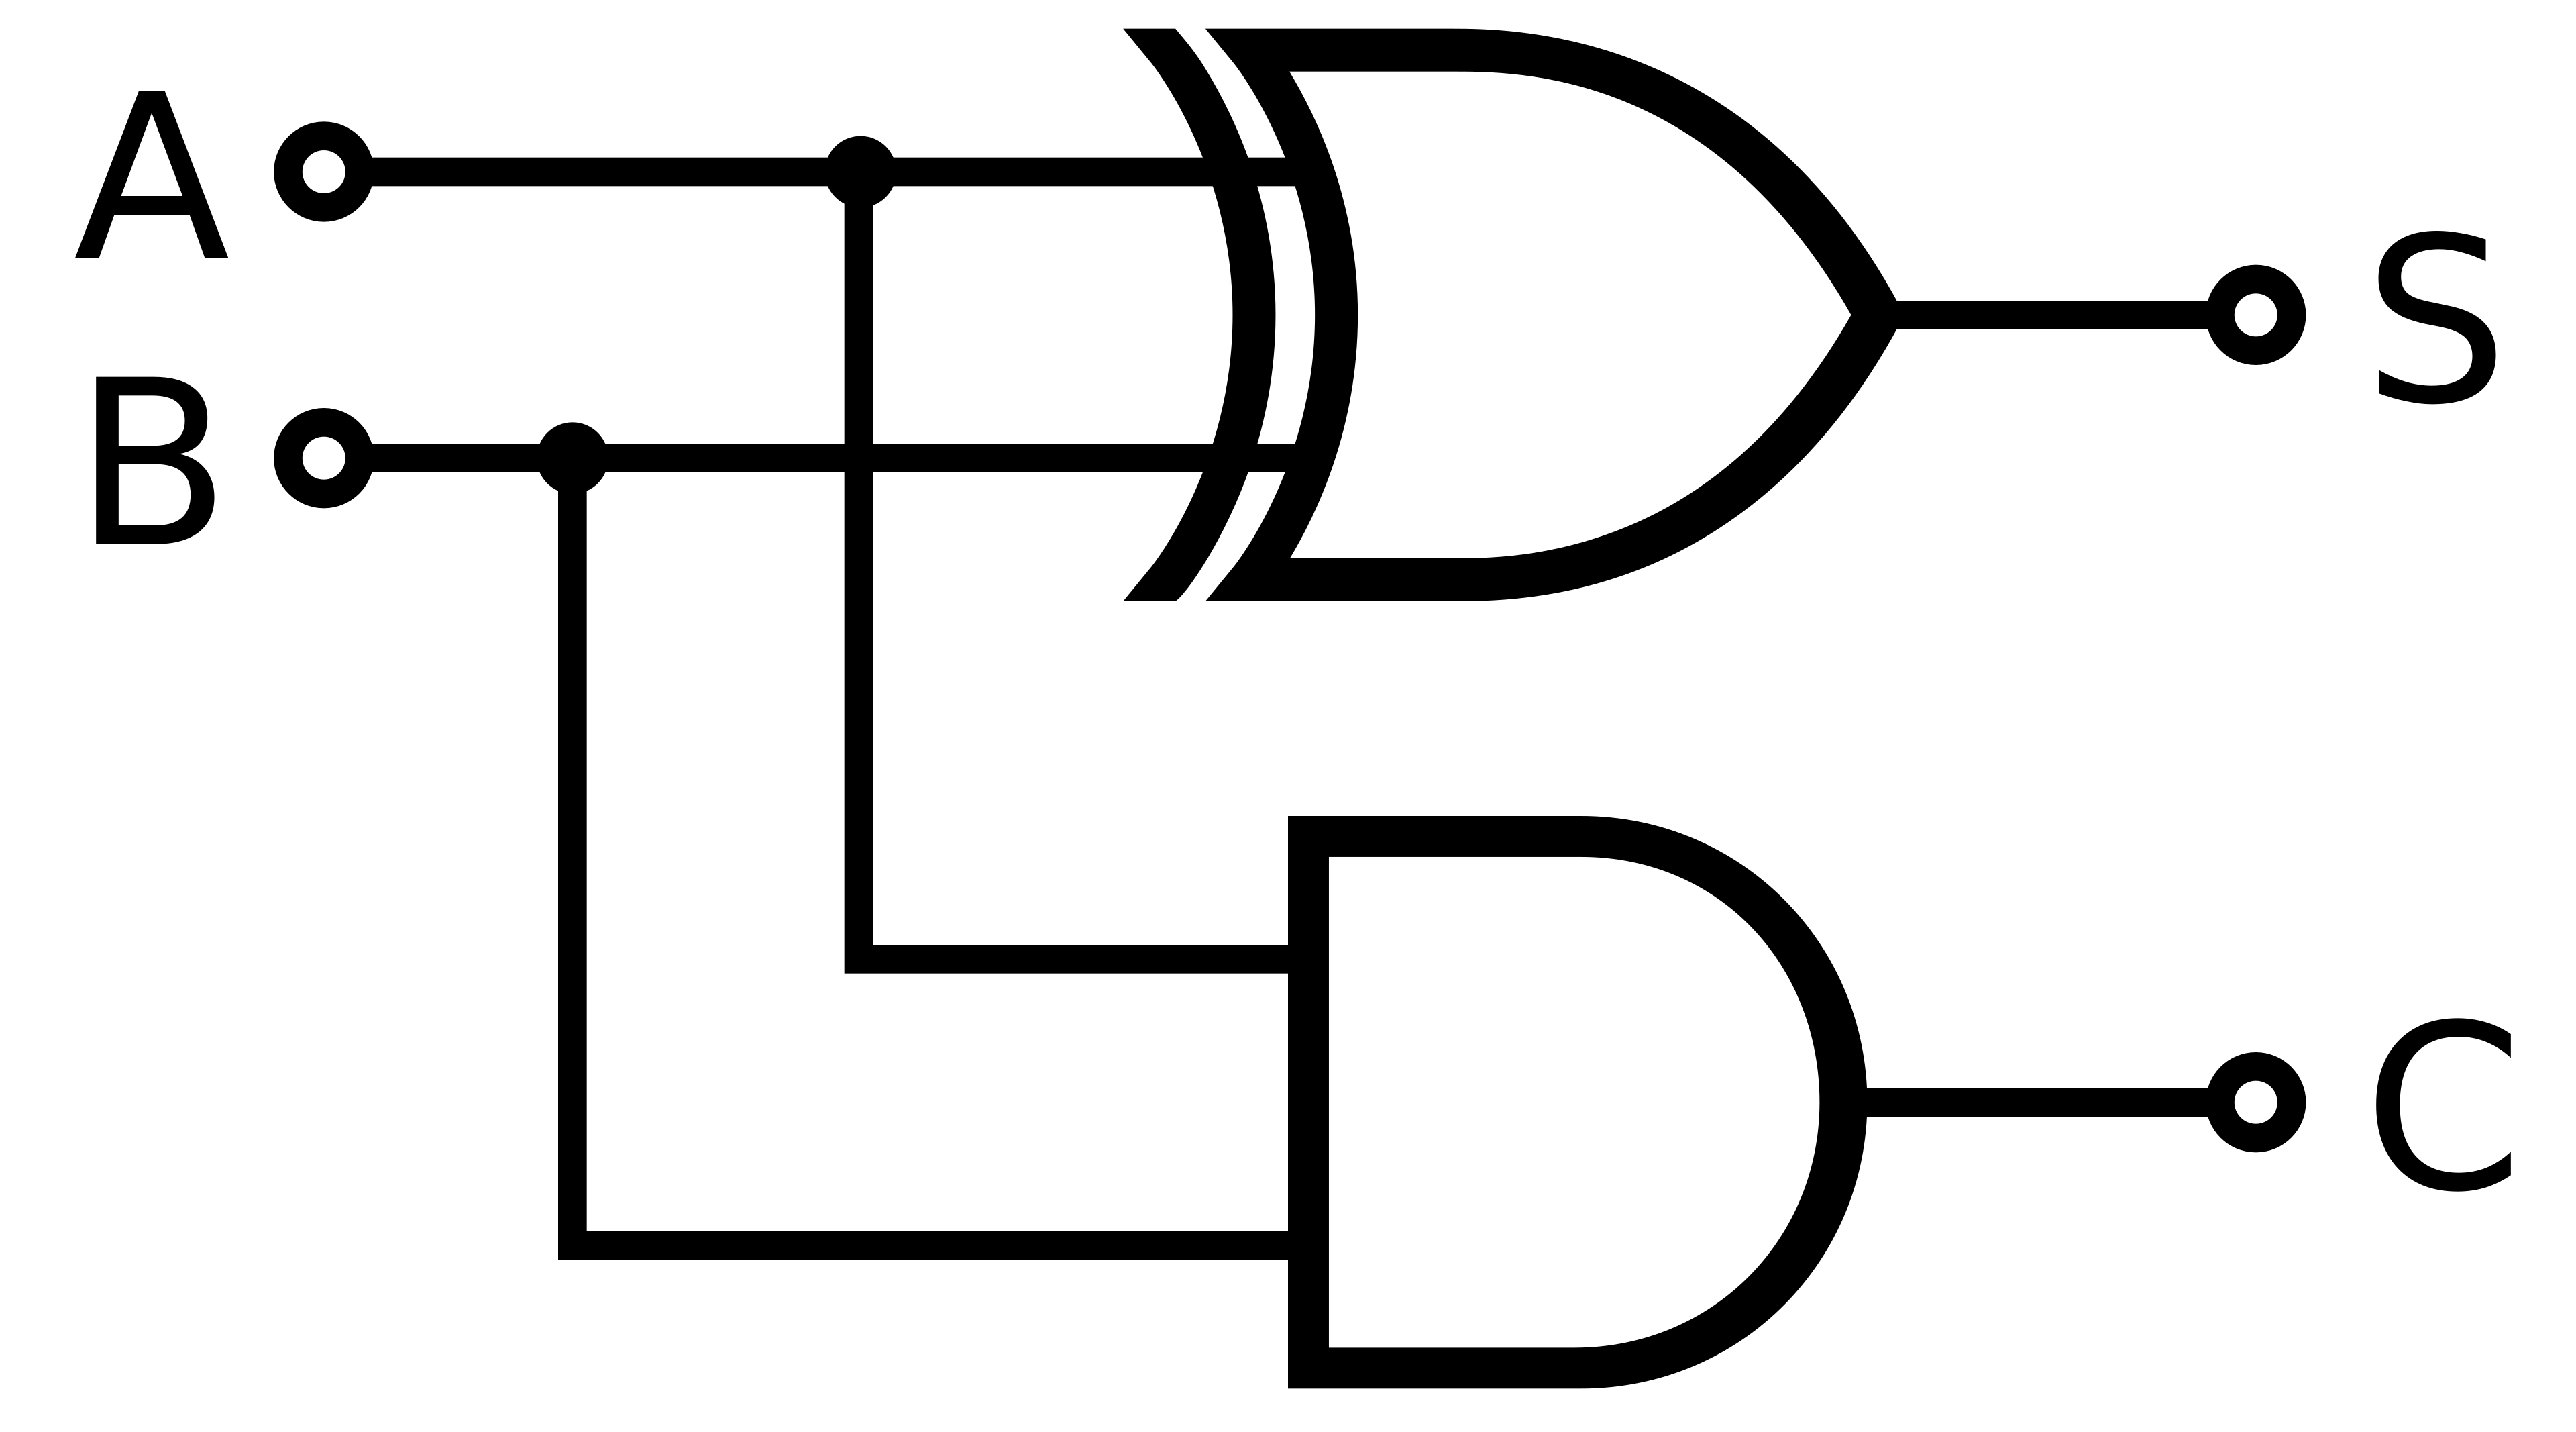
To subtract two numbers, you simply flip all the bits on the second number to yield a negation of the number, and add it to the first number as usual. To multiply two numbers, you simply perform repeated additions. You get the idea. Whether it's your refrigerator, elevator, pacemaker, car, or smartphone, nothing can function without an adder.
All mathematical software also relies on the same adder base, but with a difference:
- Since numbers on hardware are finite-sized, having a number larger than the largest slot in hardware for numbers leads to integer overflow. There is no integer overflow in math.
- Giving the hardware two numbers and getting an opaque answer back is not useful for reasoning about the underlying structure of natural numbers, and proving things based on them.
Hence, proof assistants use an explicit recursive representation of natural numbers, and this underlies all their capabilities:
inductive Nat : Type
  | zero : Nat
  | succ : Nat → Nat
We are now ready to discuss the ramifications of the construction of the silly program. At its core, it takes an input, breaks it up into tokens, encodes them into floating-point numbers, does a bit of matrix math, and prints an output. By design, the program is probabilistic, similar to the way other software picks a random default profile picture for a new user account. As a result, two equal inputs to the program seldom yield the same output. To bunch it in the same class as mathematical software is ridiculous when it is incapable of adding two numbers — to claim that somehow adding two numbers is unnecessary for "higher reasoning" is as ridiculous as claiming that knowing the alphabet is unnecessary for "higher reading". The statement "the LLM may make mistakes" is semantically incorrect, and is equivalent to the statement "the random number generator may produce a number that you don't like". To continue throwing more compute at this program with the hope that someday, it will somehow be correct is as ridiculous as continuing to add successively large even numbers with the hope that someday, it will yield a prime.
There is nevertheless fierce debate about the extent to which an LLM is correct, and several benchmarks to evaluate this, when the very notion of correctness is ill-formed in this context of this computer program. Yet, more computational resources are being poured into this program to have it be correct by chance, with the unsound justification that humans also make mistakes, and that human intelligence is also probabilistic.
With the exception of the narrow quantum regime, everything in the world is completely deterministic, including the computer program in question. Probability is a field of math to help us model and reason about macroscopic phenomenon like the economic market — it does not tell us anything about the underlying mechanics of the said phenomenon, and we use probability to talk about it precisely because we do not have an equation governing it. Probability is never a fundamental primitive except at sub-atomic scales, which are governed by the Schrödinger equation:
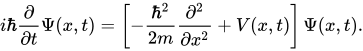
Hence, the statement "human intelligence is probabilistic" is as insightful as "the microwave sometimes doesn't work", and doesn't make a microwave similar to a car, which also sometimes doesn't work.
The silly computer program is useful for certain tasks, just as every other computer program is useful for certain other tasks. To take our earlier example:
- X >= Y is equivalent to X > Y - 1, and this holds trivially when Y - 1 does not overflow. When it does overflow, it must be INT_MAX, and the comparison would evaluate to false anyway.
Using mathematical reasoning to fix it, and a tool to check it, we get a correct statement:
- X > Y - 1 implies X >= Y, and this holds trivially when Y - 1 does not overflow. When it does overflow, it must be INT_MAX, and the comparison would evaluate to false anyway.
Now, if I patch LLVM to use this property to perform optimizations, the LLM can faithfully generate tests to cover it for me. How exactly? It would generate a lot of rubbish, run it through the unpatched and patched compiler, and run diff: when diff returns 0 (the files are identical), it would mutate the rubbish and repeat the process iteratively until diff returns 1 (the files differ). The program reminds us of csmith and indeed belongs to that class of software. What it never has been able to, and will never be able to do, is to point out the faulty equivalence and fix it with the implication — there is obviously no computer program that can do this today, as we don't have the faintest clue about what intelligence is.
The breakthrough Navier-Stokes result was achieved in a very similar way — lean was used in place of diff. To infer from this that the generator program has mathematical capabilities is obviously unsound.